Install
pip install evalviewRepository reader
Explore before you clone
Read the project’s README, skills and supporting Markdown here. Rendered view is shown first; source is one click away when you need the exact text.
Public files are loaded on demand from the repository. The atlas does not copy or modify them.
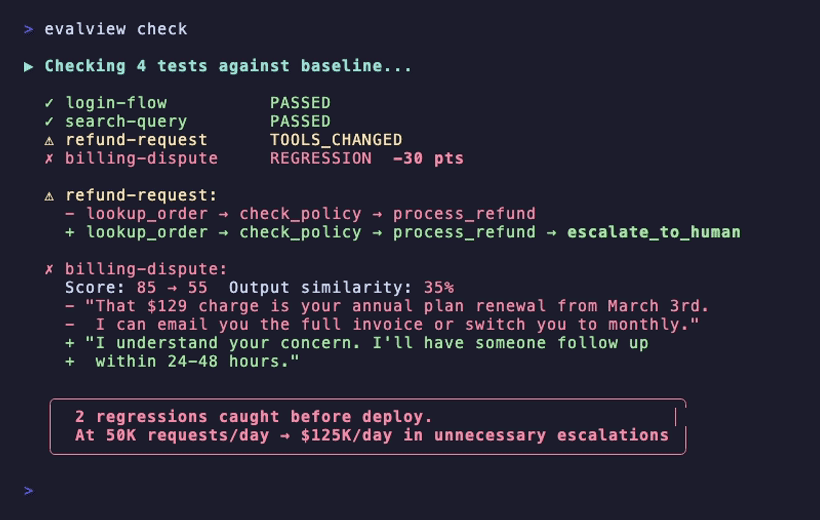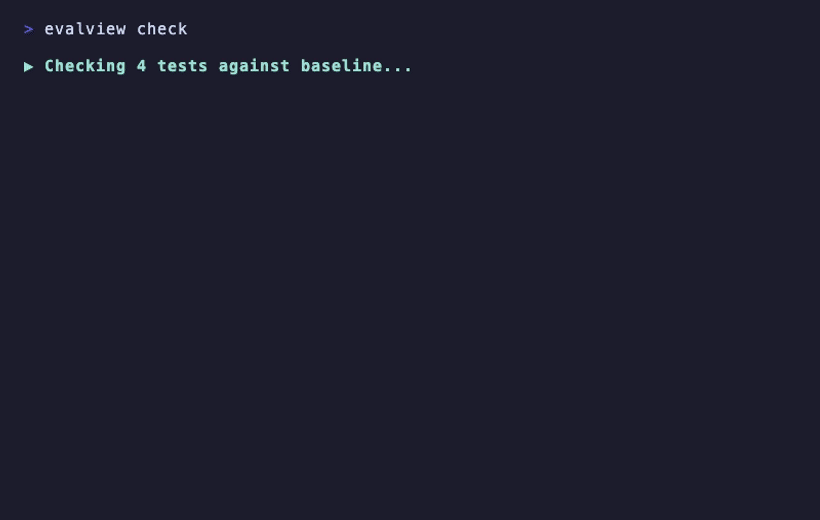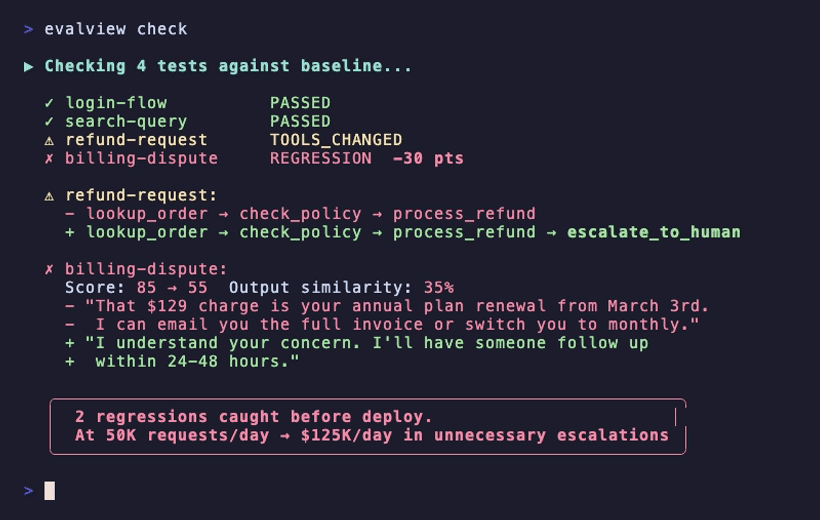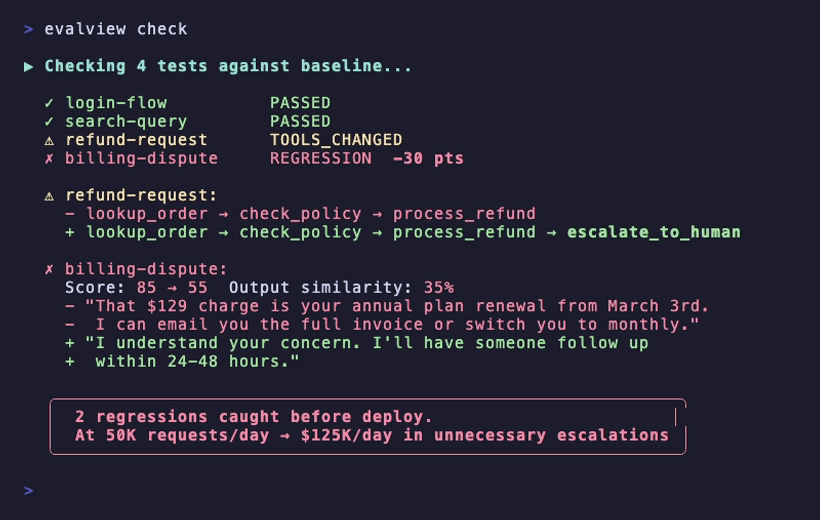
Screenshot
Platform support
| Platform | Runs here | On what evidence |
|---|---|---|
| Windows | Likely | Inferred from the language or runtime. Nothing in the project says so. |
| WSL2 | Likely | Inferred from the language or runtime. Nothing in the project says so. |
| macOS | Likely | Inferred from the language or runtime. Nothing in the project says so. |
| Linux | Likely | Inferred from the language or runtime. Nothing in the project says so. |
| Docker | No | No evidence of support anywhere in the project. |
Where it came from
Named by 3 of the 39 lists the atlas merges, independently of each other.
- LLMOps (tensorchord)
- MCP Servers (punkpeye)
- Prompt Engineering (promptslab)
How it is classified
One topic, 4 harnesses. Each link is a prerendered page of everything else in that slice.
Related in Observability & Evals
Closest first — projects that plug into the same harnesses, then the ones the most lists agreed on.
- runtapeRehanMohammed985/runtapeFinds which part of an agent's context caused a bad decision by rerunning it with pieces removed, checks candidate fixes the same way, and writes a…
- Codeburngetagentseal/codeburnFree, local tool that tracks AI coding token usage and cost across 31 tools and agents by model, project, and task. Worth including because…
- Opikcomet-ml/opikComet's open-source AI observability and evaluation platform: deep tracing of LLM calls, conversation logging, and agent activity, plus built-in…
- AgentOpsAgentOps-AI/agentopsOpen-source agent engineering platform (YC W24) with session replay, cost tracking, and failure detection across 10+ frameworks including CrewAI…
- BitRouterbitrouter/bitrouterAgent-native LLM router that optimizes your agent with every run — zero harness changes, with every model call reliable, traceable, secure, and…
- budget-guardkimbeomgyu/budget-guardZero-infra hard spending caps for LLM APIs — blocks before overspending (atomic reservation), per-feature cost attribution, streaming usage…
- Claude Code Agent Monitorhoangsonww/Claude-Code-Agent-Monitorby hoangsonww - A self-hosted real-time dashboard that monitors Claude Code agent activity via its native hooks — live sessions, subagent…
- cloneproofpcjansen09-max/cloneproofMeasures how closely an agent-built website clone matches the original and returns per-element differences plus a fix prompt for the agent's next…